
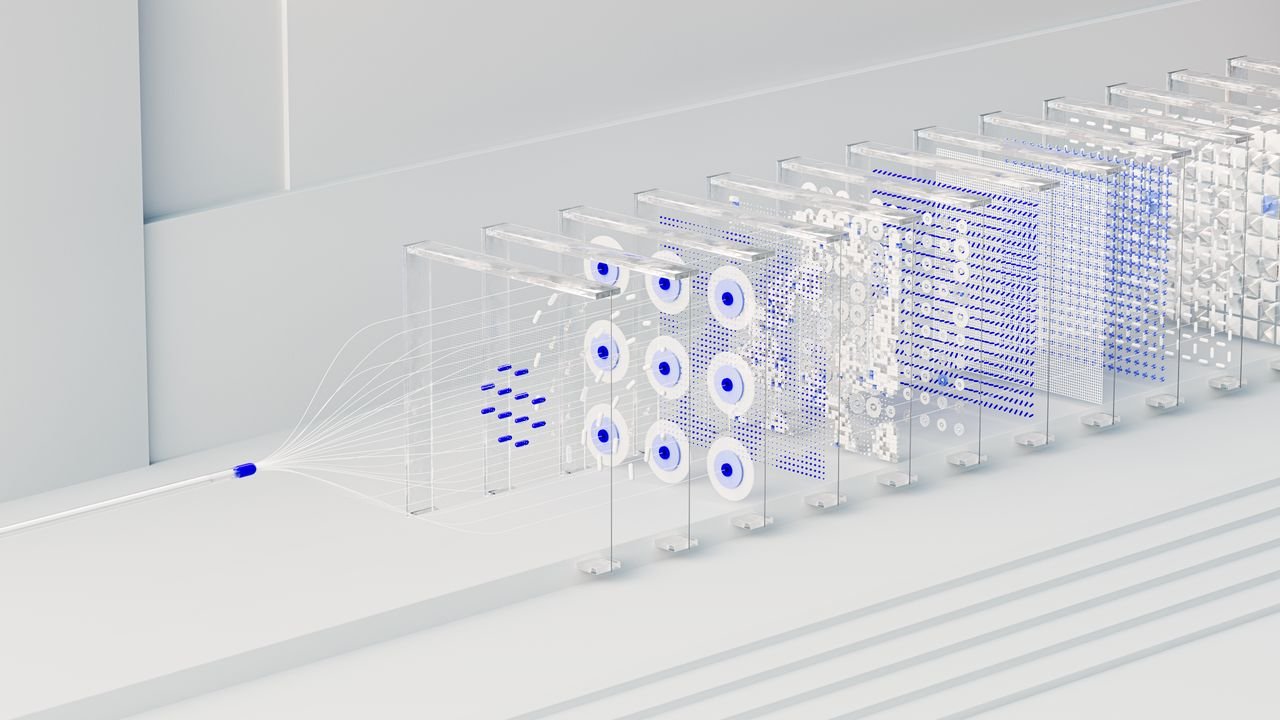
Machine Learning (ML) powers everything from streaming recommendations and spam filters to medical diagnostics and fraud detection. At its core, Machine Learning is a branch of artificial intelligence where computers learn to perform tasks by finding patterns in data—without being explicitly programmed with rigid, hard-coded rules.
Understanding how machine learning works requires looking at its main learning approaches and the foundational algorithms that drive them.
The Core Concept: How Machines Learn
Traditional software relies on a human writing explicit instructions: Data + Rules = Answers.
Machine Learning flips this formula: Data + Answers = Rules.
Instead of coding rules, you feed an ML system historical data along with the correct outcomes. The system uses mathematical algorithms to identify relationships within the data, creating a statistical model. Once trained, this model accepts new, unseen data and outputs accurate predictions.
The 3 Main Types of Machine Learning
Machine learning tasks fall into three main paradigms based on how the system receives data:
-
Supervised Learning: The model trains on labeled data (input data paired with the correct target answer). Think of it like a student learning with an answer key.
-
Unsupervised Learning: The model analyzes unlabeled data to uncover hidden patterns, groupings, or structures on its own.
-
Reinforcement Learning: An agent learns by trial and error within an environment, receiving rewards for correct actions and penalties for mistakes.
Key Machine Learning Algorithms Explained
Algorithms are the mathematical engines that make learning possible. Here are six essential algorithms broken down simply:
1. Linear Regression (Predicting Continuous Numbers)
-
Paradigm: Supervised Learning
-
How It Works: Draws the best possible straight line through data points to show relationships between variables.
-
Simple Analogy: Estimating a home’s sale price based on square footage. As square footage goes up, price tends to rise at a predictable rate.
2. Logistic Regression (Binary Classification)
-
Paradigm: Supervised Learning
-
How It Works: Despite its name, this algorithm calculates probabilities to classify data into two distinct categories (Yes/No, 0/1).
-
Simple Analogy: Determining whether an email is “Spam” or “Not Spam” based on specific keyword frequencies.
3. Decision Trees (Rule-Based Decisions)
-
Paradigm: Supervised Learning
-
How It Works: Splits data into branches based on simple conditional questions (e.g., Is income > $50,000?), creating a tree-like flowchart of decisions.
-
Simple Analogy: Playing a game of 20 Questions where every yes/no answer narrows down the options until reaching a final conclusion.
4. Random Forest (Strength in Numbers)
-
Paradigm: Supervised Learning
-
How It Works: Combines dozens or hundreds of individual decision trees trained on random subsets of the data. The final output is decided by a majority vote among all trees.
-
Simple Analogy: Asking a panel of 50 diverse experts for financial advice instead of relying on a single advisor’s opinion.
5. K-Means Clustering (Grouping Similar Items)
-
Paradigm: Unsupervised Learning
-
How It Works: Identifies natural clusters in data by placing central points (centroids) and grouping nearby data items together based on shared characteristics.
-
Simple Analogy: Sorting a pile of unsorted laundry into distinct groups (dark clothes, whites, towels) without prior instructions.
6. Neural Networks (Complex Pattern Recognition)
-
Paradigm: Supervised / Unsupervised Learning
-
How It Works: Inspired by human brain biology, interconnected layers of nodes (neurons) pass signals to process complex, non-linear patterns like imagery, audio, or natural language.
-
Simple Analogy: An assembly line where each worker checks a tiny detail before passing the product down the line to form a complete understanding.
Summary Comparison of Key Algorithms
| Algorithm | Learning Type | Primary Use Case | Key Advantage |
| Linear Regression | Supervised | Predicting continuous metrics (e.g., sales revenue) | Fast, simple, highly interpretable |
| Logistic Regression | Supervised | Binary classification (e.g., churn vs. retain) | Easy to implement for two-class problems |
| Decision Trees | Supervised | Step-by-step decision making | Easy for humans to visualize and trace |
| Random Forest | Supervised | Complex classification and regression | Reduces errors and handles missing data well |
| K-Means Clustering | Unsupervised | Customer segmentation, anomaly detection | Automatically groups unstructured data |
| Neural Networks | Deep Learning | Image recognition, speech, LLMs | Handles massive, unstructured data sets |